




MSc Computer Science student at Aalborg University · Machine learning research · LLMs · Recommender systems


I'm a master's student in computer science at Aalborg University, Denmark, working on machine learning research. I care about the gap between what machine learning methods are claimed to do and what they actually do, so I analyse methods from first principles, reproduce published results under controlled conditions, and build small, well-tested research software that makes results easy to verify.
- Machine learning research: how training choices such as loss functions, reweighting and regularisation change what a model actually learns, backed by proofs and controlled experiments.
- LLMs and generative AI: parameter-efficient fine-tuning with LoRA and QLoRA, 4-bit quantisation, and open models such as Qwen.
- LLM inference optimisation: distilling large language models into smaller, faster ones, the topic of my bachelor's project.
- Recommender systems: multimodal and cold-start recommendation, graph-based recommenders, and the reproducibility of published models.
- Reproducible research: controlled experiments, sound statistics, and long training runs on GPU clusters.


Distil an LLM classification prompt into a small, fast model that runs on a CPU. Describe the task in a short YAML file and give it unlabelled texts: an instruction-tuned LLM labels them with soft targets, a small encoder learns to imitate them, and the result is exported to ONNX, optionally int8. It continues my bachelor's project on inference optimisation by distilling LLMs.
Try the live demo · Documentation · Code · pip install tinydistill
flowchart LR
    A["Task prompt +<br/>unlabelled texts"] --> B["LLM teacher(s)<br/>Qwen · Mistral · Phi · ..."]
    T["tune: check the<br/>task file"] -.-> B
    S["Synthetic texts<br/>(synth)"] -.-> B
    V["vLLM server ·<br/>hosted API"] -.-> B
    K["A few gold labels<br/>per class"] -.-> B
    K -.-> C
    B -- "soft labels<br/>(ensembled)" --> C["Small encoder<br/>student"]
    C --> D["ONNX / int8<br/>export"]
    D --> E["Fast CPU<br/>inference"]
    D --> W["Browser · server · Hub ·<br/>Python (Distiller)"]
    E -.-> F["Cascade: unsure<br/>texts to the LLM"]
Results on Banking77 (77 intents, 3,080 held-out test texts; latency per text on an RTX 4090 for the teacher and 2 CPU threads for the students; the students learn from the teacher's soft labels plus 8 gold labels per class; all benchmarks):
| Model | Runs on | Accuracy | Latency | Size | Speed-up |
|---|---|---|---|---|---|
| Teacher: Qwen2.5-7B, 4-bit, 8-shot | GPU | 0.783 | 264 ms | 5.4 GB | 1x |
| Student: MiniLM-L6, int8 | CPU | 0.814 | 1.2 ms | 23 MB | 214x |
| Student: static embeddings, int8 | CPU | 0.802 | 0.1 ms | 8 MB | 3244x |
The students are more accurate than their teacher and hundreds of times faster on a CPU than the teacher on a GPU.
|
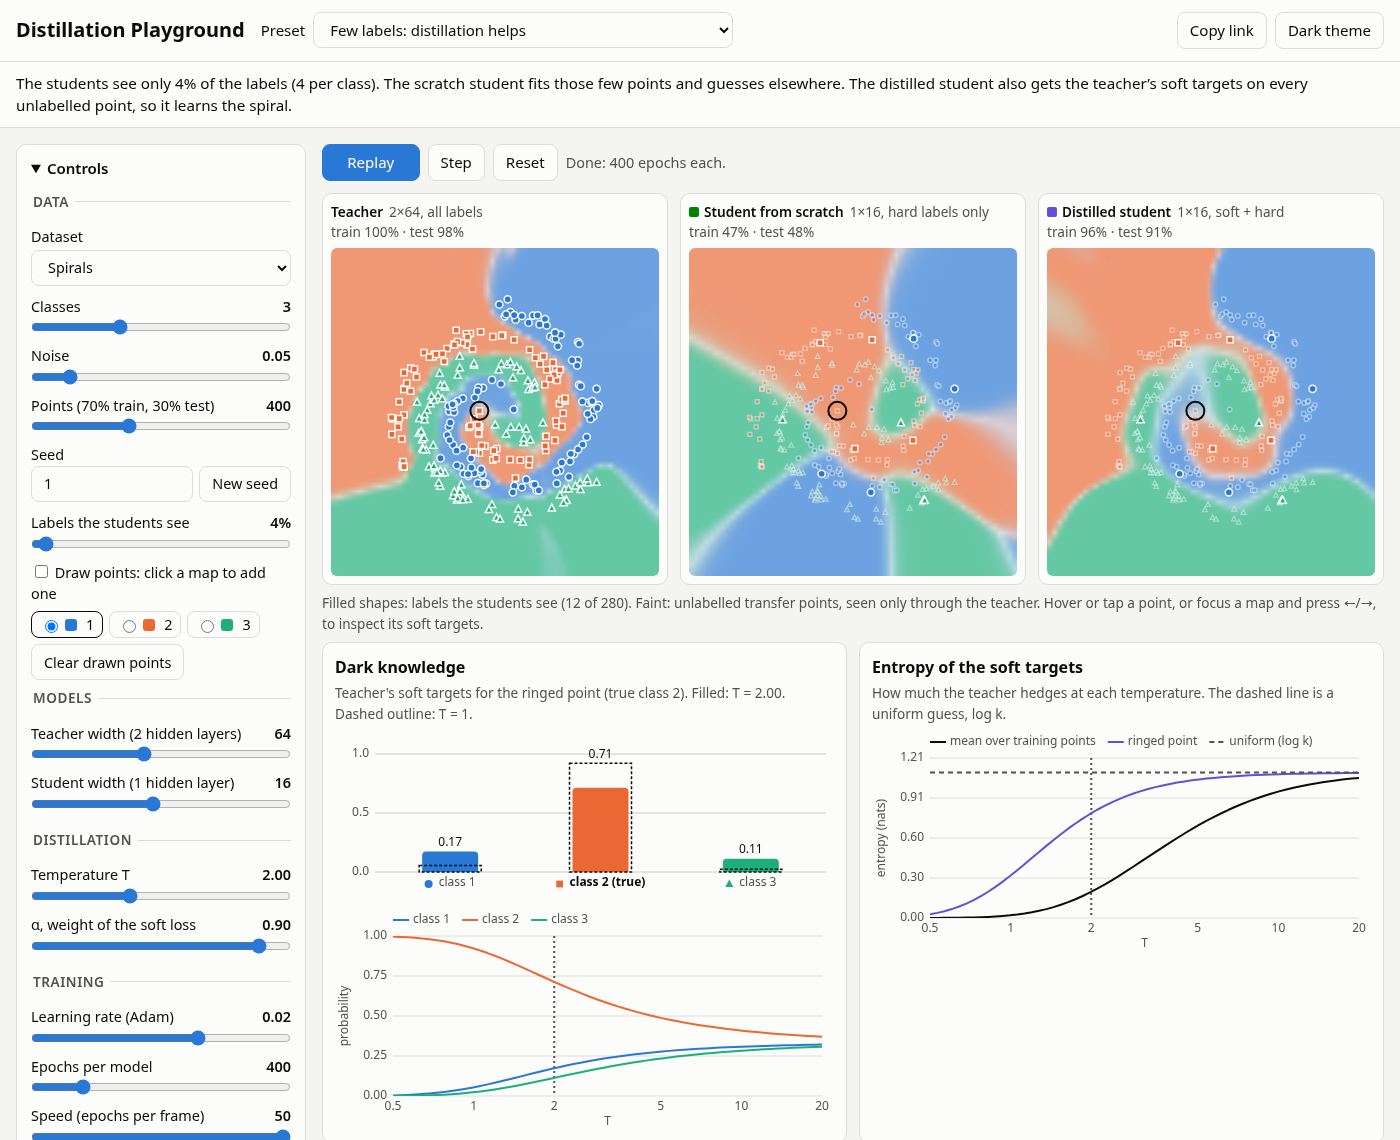
An interactive, in-browser demo of knowledge distillation. A teacher network and two small students train side by side on 2D data, one from the labels alone and one from the teacher's soft targets; sliders for the temperature, the mixing weight and the student size show when distillation helps. Written from scratch in TypeScript, with no ML library and gradient-checked backpropagation.
Try the live demo · Code |
|
Mathematical bugs I found and reported in widely used ML libraries, each with a minimal reproduction, and fixed in a pull request where I could.
| Library | Finding | Status |
|---|---|---|
| transformers | Doge's load-balancing loss paired expert loads (by expert id) with router probabilities in sorted rank order | Fix merged |
| transformers | Doge's MoE router reshape mixes tokens, so its logits depend on future tokens and other sequences in the batch | Issue |
| transformers | TopHLogitsWarper does not implement the documented Top-H rule |
Issue |
| transformers | ClapModel(return_loss=True) computes the text-to-audio loss twice and never the audio-to-text loss |
Issue |
| PyTorch | kl_divergence of transformed distributions returns the base KL for non-injective transforms |
Issue |
| PyTorch | kl_divergence(Wishart, Wishart) is wrong for batched distributions and has no gradient with respect to p |
Issue |
| PyTorch | kl_divergence(Categorical, Categorical) gives a NaN gradient when p has -inf logits |
Issue |
| PyTorch | torch.sparse.mm on CUDA is nondeterministic, and deterministic mode neither fixes nor flags it |
Issue |
| Keras | sparse_categorical_crossentropy(from_logits=True) returns NaN on JAX and NumPy for -inf non-target logits |
PR |
| Keras | Focal cross-entropy with from_logits=True saturates, so confidently wrong logits get zero gradient |
PR |
| Keras | CutMix's factor is the range of the Beta concentration, not of the mixing weight |
PR |
| bitsandbytes | LAMB and LARS never update a zero-norm parameter (zero-initialised biases, LoRA B matrices) | PR |
| lighteval | The standard error of averaged rows is the mean of the subtask errors, about 7x too large on MMLU | PR |
| TensorFlow Probability | KL divergence of transformed distributions with a non-injective bijector returns the base KL | PR |
| solo-learn | The SupCon loss is the paper's L_in, not the L_out it specifies (Khosla et al. 2020, Eq. 2) | PR |
| diffusers | --logit_mean shifts SD3 training timesteps in the opposite direction to the paper |
Issue |
| NVIDIA Merlin | The logQ correction is applied before the temperature, which biases sampled-softmax training towards popular items (models, Transformers4Rec); unique log-uniform sampling keeps the smallest ids | Issue |
Languages
Machine learning





Methods and models
LoRA QLoRA PEFT Quantisation Knowledge distillation Inference optimisation Hashing Qwen Transformers
Recommender systems Graph neural networks Multimodal learning Class imbalance Statistical testing
Closed-form recommenders Cold-start recommendation Pre-registered evaluation
Research and infrastructure


Web (earlier projects)
- MSc in Computer Science, Aalborg University (ongoing)
- BSc in Computer Science, Aalborg University, with a bachelor's project on inference optimisation by distilling LLMs
- Writing up research on machine learning training objectives
- Pre-thesis project on reproducibility and cold-start ranking in multimodal recommender systems
- Auditing ML libraries for mathematical bugs (contributions)
- Open to collaborations on machine learning research and tooling

"Measure what models actually learn, not what they are claimed to learn."